EVM Stack Explained: 256-Bit Words, Opcodes, and Stack Too Deep
Learn how the EVM stack executes Ethereum bytecode, how PUSH, DUP, SWAP, and arithmetic opcodes move 256-bit words, and why stack errors happen.
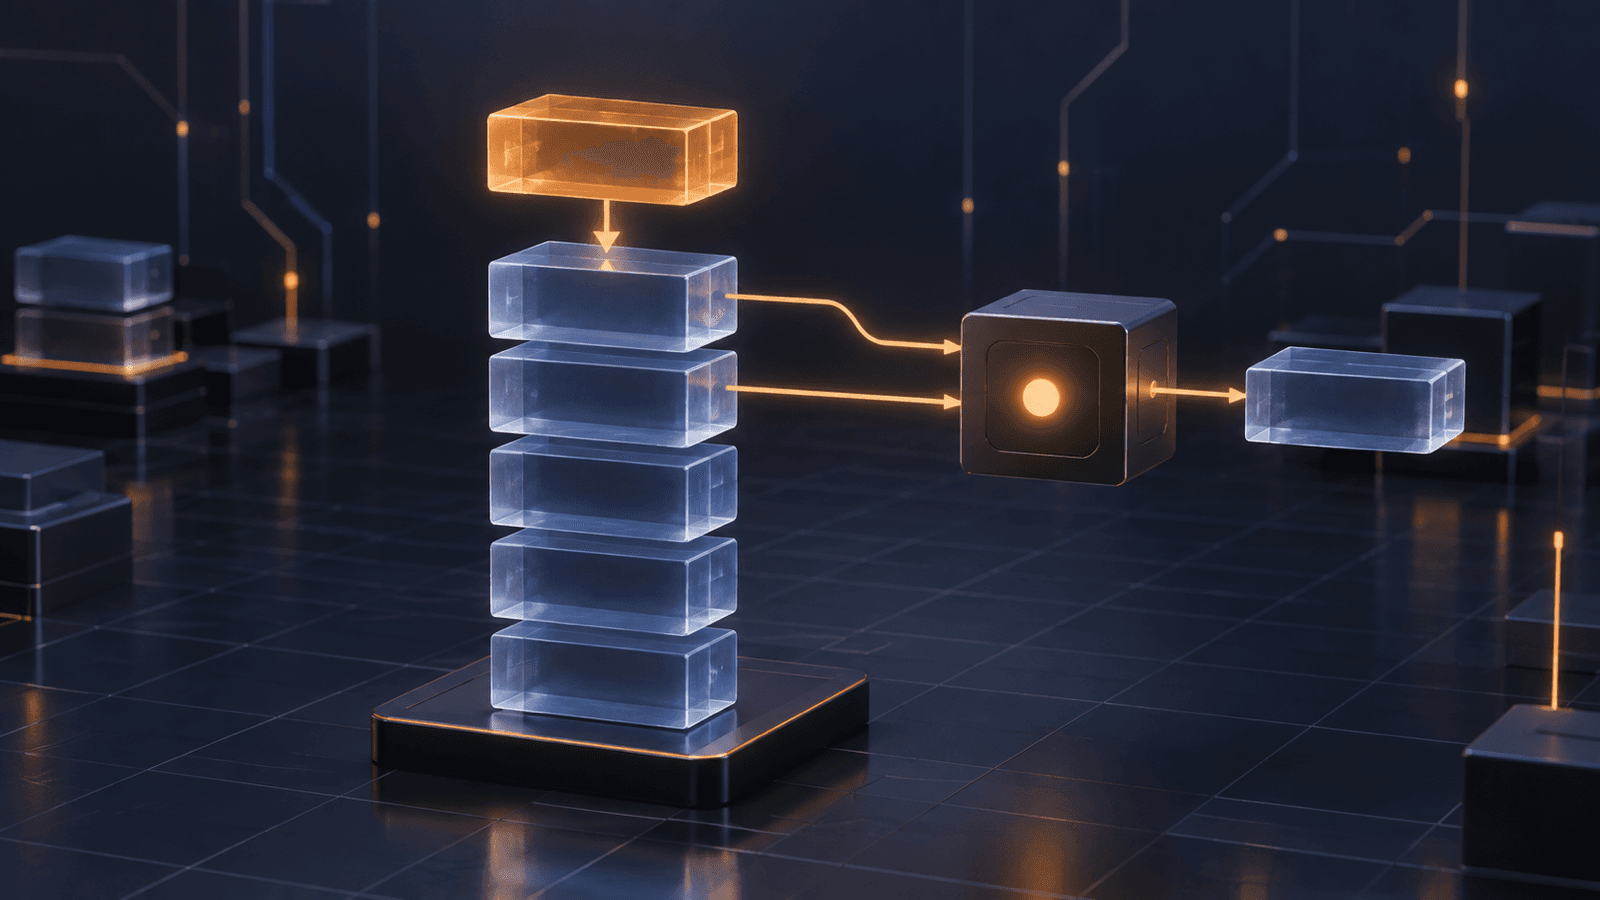
Solidity hides most low-level bookkeeping, but a transaction trace quickly exposes rows of pushes, duplicates, swaps, and arithmetic. The missing mental model is the EVM stack: the small working area where Ethereum bytecode keeps operands and intermediate results. It connects practical blockchain basics to what every opcode actually consumes and produces.
Think of it as a stack of cafeteria trays. You can place a tray on top, remove the top tray, copy one of the nearby trays, or swap the top with another nearby tray. You cannot reach into the middle as freely as you would address a memory array. That last-in, first-out constraint makes bytecode execution predictable, but it also explains confusing traces and compiler errors.
What the EVM stack is
The Ethereum Virtual Machine is a stack machine. According to the official Ethereum EVM documentation, its operand stack can hold at most 1,024 items, and every item is a 256-bit word. One word is 32 bytes, whether the current value represents a small integer, an address, a Boolean, or a pointer into another data area.
The stack begins empty in a new execution frame. Bytecode instructions—opcodes—change it one step at a time. Most instructions pop their inputs from the top and push a result back. The stack is temporary: it is not contract storage, and it does not persist after the frame finishes.
The word stack can refer to two different limits in Ethereum discussions:
- The operand or expression stack holds the values used by opcodes.
- The call depth counts nested message calls between execution frames.
Both limits have historically used the number 1,024, but Solidity's security documentation explicitly warns that they are unrelated. A “stack too deep” compiler message is also not proof that a contract approached 1,024 runtime items; it usually reflects how the compiler can arrange simultaneously live values within the instruction set's directly reachable stack window.
How stack execution works
Each opcode has a defined stack input and output. Ethereum.org's opcode reference shows these shapes directly. ADD, for example, consumes two words and pushes their sum modulo 2²⁵⁶. POP consumes one word and produces none.
Here is a tiny bytecode sequence:
60 02  // PUSH1 0x02   stack: [2]
60 03  // PUSH1 0x03   stack: [3, 2]
01     // ADD           stack: [5]
50     // POP           stack: []
In this notation, the leftmost item is the top. PUSH1 reads the next byte from code and places it on the stack. After the second push, ADD removes 3 and 2, computes the result, and pushes 5. POP then discards it.
This is like a calculator that keeps intermediate answers on a pile rather than in named registers. Solidity variables make source code readable, while the compiler plans the pushes, loads, duplicates, and spills needed to realize those variables in bytecode.
PUSH, DUP, SWAP, and POP
Four opcode families expose the stack model most clearly.
PUSH places constants on top
PUSH0 places zero on the stack. PUSH1 through PUSH32 read between one and 32 immediate bytes from the bytecode and push the value as a 256-bit word. A short constant can use a short instruction even though its resulting stack slot is still one full word.
DUP copies a reachable item
DUP1 copies the top item; DUP16 copies the sixteenth item to the top. The original remains in place. This is how bytecode can reuse a nearby value without destroying it.
SWAP changes local order
SWAP1 exchanges the top item with the second item. The family extends through SWAP16, which exchanges the top with the seventeenth item. These instructions rearrange values without changing the stack height.
POP removes the top
POP drops one item. Compiled code uses it when a value is no longer needed. In carefully written bytecode, every branch must maintain a layout that later instructions understand.
The classic DUP1–DUP16 and SWAP1–SWAP16 ranges are why “the stack holds 1,024 values” and “the compiler can directly reach only a small window” are different statements. Most of the stack capacity is not randomly addressable through those legacy instructions.
Stack vs memory, storage, and calldata
The stack is only one EVM data area. Treating all four as interchangeable leads to bad gas estimates and unsafe assembly.
| Area | What it holds | Addressing model | Lifetime |
|---|---|---|---|
| Stack | Operands and intermediate 256-bit words | Top-oriented with opcode-defined access | Current execution frame |
| Memory | Mutable temporary bytes | Byte offsets; expands as accessed | Current execution frame |
| Calldata | Read-only call input bytes | Byte offsets | Current execution frame |
| Storage | Persistent contract state | 256-bit keys to 256-bit values | Across transactions |
The stack often carries a pointer rather than the whole object. A dynamic byte array can live in EVM memory, while a stack word holds its offset. A state variable lives in contract storage slots, while SLOAD consumes a storage key from the stack and pushes the loaded value. CALLDATALOAD similarly takes an offset and pushes 32 bytes derived from calldata.
That distinction is essential when reading a trace. Seeing a large hexadecimal word on the stack does not tell you whether it is money, an address, a signed integer, a hash, or a pointer. Meaning comes from the opcode sequence, ABI, and execution context.
Why “stack too deep” happens in Solidity
High-level Solidity lets you name many parameters, return values, and local variables. The compiler must map live values into stack positions and sometimes memory. If too many values must remain available at once, a code-generation path can fail with a “stack too deep” error even though the EVM's absolute depth limit is far away.
Official Solidity Yul documentation explains that Yul variables are normally assigned stack slots and that referencing a variable becomes a DUP operation in EVM code. It also describes a stack-limit-evader optimization that can move otherwise unreachable variables into memory when its safety conditions are met.
Practical remedies depend on the code and compiler version:
- Reduce how many values are live in one expression or block.
- Split a large function into meaningful internal helpers.
- Group related inputs in a struct when that improves the API, not merely to silence an error.
- Remove locals that duplicate values already available.
- Compare the normal and IR-based compiler pipelines with tests and gas measurements.
Do not toggle optimizer or viaIR settings blindly. Solidity documents two code-generation routes and their semantic differences in its IR-based codegen guide. Pin the compiler version, inspect its known bugs list, and retest deployment bytecode and behavior before shipping.
Failure modes and security risks
Stack underflow
An opcode cannot pop values that are not present. The official Yellow Paper walkthrough lists insufficient stack items as an exceptional halt. Hand-written or dynamically analyzed bytecode must account for every branch's input height.
Stack overflow
Execution also halts exceptionally if an instruction would leave more than 1,024 items. Compilers normally prevent this in generated code, but interpreters, analyzers, and bytecode authors still need to enforce the consensus rule exactly.
Wrong operand order
Addition hides ordering mistakes because it is commutative. Subtraction, division, comparisons, memory writes, calls, and returns do not. When reading a trace, use the current fork's opcode table instead of guessing which displayed end is the top.
Confusing values with pointers
A valid-looking offset can still point outside intended memory or calldata bounds. A storage key can identify a completely different state slot. Inline assembly bypasses several high-level checks, so validate lengths, offsets, types, and return data rather than trusting a value because it fits in 256 bits.
Assuming every EVM chain is identical
EVM-compatible networks can activate opcodes and gas schedules on different timelines. Compile for the intended target and verify the active fork. A trace decoded with the wrong instruction set can be misleading.
A practical stack-trace checklist
- Confirm the chain, block, and active EVM revision
- Mark which side of the trace display is the stack top
- Record each opcode's required inputs and produced outputs
- Track stack height across every branch and jump destination
- Distinguish literal values from memory offsets and storage keys
- Decode signedness and narrower Solidity types explicitly
- Compare source maps and compiler settings with deployed bytecode
- Reproduce suspicious paths in a local fork or debugger
- Treat inline assembly and untrusted return data as review hotspots
FAQ
Is the EVM stack persistent?
No. It belongs to the current execution frame. Persistent contract state lives in storage.
Is one stack item always 32 bytes?
Each stack item is a 256-bit word. A smaller Solidity value can occupy a word, and unused high bits may require cleaning before low-level use. Its source-level type is not stored as a runtime label on the stack.
Does stack depth mean contract call depth?
No. The operand stack and nested message-call depth are separate mechanisms. Do not diagnose one limit from the other's number.
Is the stack cheaper than memory?
This is not a useful universal comparison. Stack manipulation opcodes have their own costs and access limits; memory supports byte-addressed temporary data and charges for expansion. The compiler chooses layouts across both. Measure the compiled path under the target fork.
Should I write raw EVM bytecode to optimize gas?
Only with a strong reason and extensive testing. Hand-written bytecode can reduce abstraction overhead in narrow cases, but it removes compiler checks and makes stack balance, control flow, fork compatibility, and auditing your responsibility.
Primary sources
- Ethereum.org: Ethereum Virtual Machine
- Ethereum.org: EVM Opcode Reference
- Ethereum Yellow Paper: Formal EVM Specification
- Ethereum.org: Understanding the Yellow Paper's EVM Specification
- Solidity: Yul
- Solidity: IR-Based Code Generation Changes
- Solidity: List of Known Bugs
The stack is a small execution ledger
The EVM stack records the immediate state of computation: which operands are ready, which intermediate values remain live, and what the next opcode can legally consume. Once you see bytecode as a series of stack-shape transitions, traces become less like walls of hex and more like a reproducible calculation.
This guide is educational and not financial advice. Smart-contract defects and crypto assets can cause complete loss. Verify current specifications, test the exact compiler and fork you use, risk only amounts you can afford to lose, and do your own research (DYOR).
Keep learning
EVM Memory Explained: Layout, Expansion Gas, and Solidity Safety
Learn how EVM memory works, why expansion costs gas, how Solidity uses the free memory pointer, and which assembly mistakes can corrupt execution.
 GOMTU8 min read
Ethereum Contract Storage Slots: Packing, Mappings, and eth_getStorageAt
Learn how Solidity assigns Ethereum contract storage slots, how mappings and arrays derive locations, and how to inspect state safely with eth_getStorageAt.
GOMTU9 min read
Ethereum Calldata Explained: How to Decode Transaction Input Data
Learn how Ethereum calldata encodes function selectors and arguments, how explorers decode it, and what to verify before signing a contract transaction.
GOMTU6 min readExplore related topics
Ethereum Glamsterdam Upgrade: ePBS, BALs, and What Is Actually Planned
Ethereum Glamsterdam is expected in Q4 2026. Learn its frozen scope, Sepolia milestone, ePBS, block-level access lists, and remaining uncertainties.
GOMTU7 min readCrypto Address Poisoning: How to Verify Wallet Addresses Before You Send
Crypto address poisoning plants a lookalike address in your transaction history. Learn how it works and follow a safer verification checklist.
GOMTU7 min read