Ethereum SSZ Explained: Serialization, Merkleization, and Proofs
Learn how Ethereum Simple Serialize turns consensus data into bytes and Merkle roots, including types, offsets, generalized indices, and limitations.

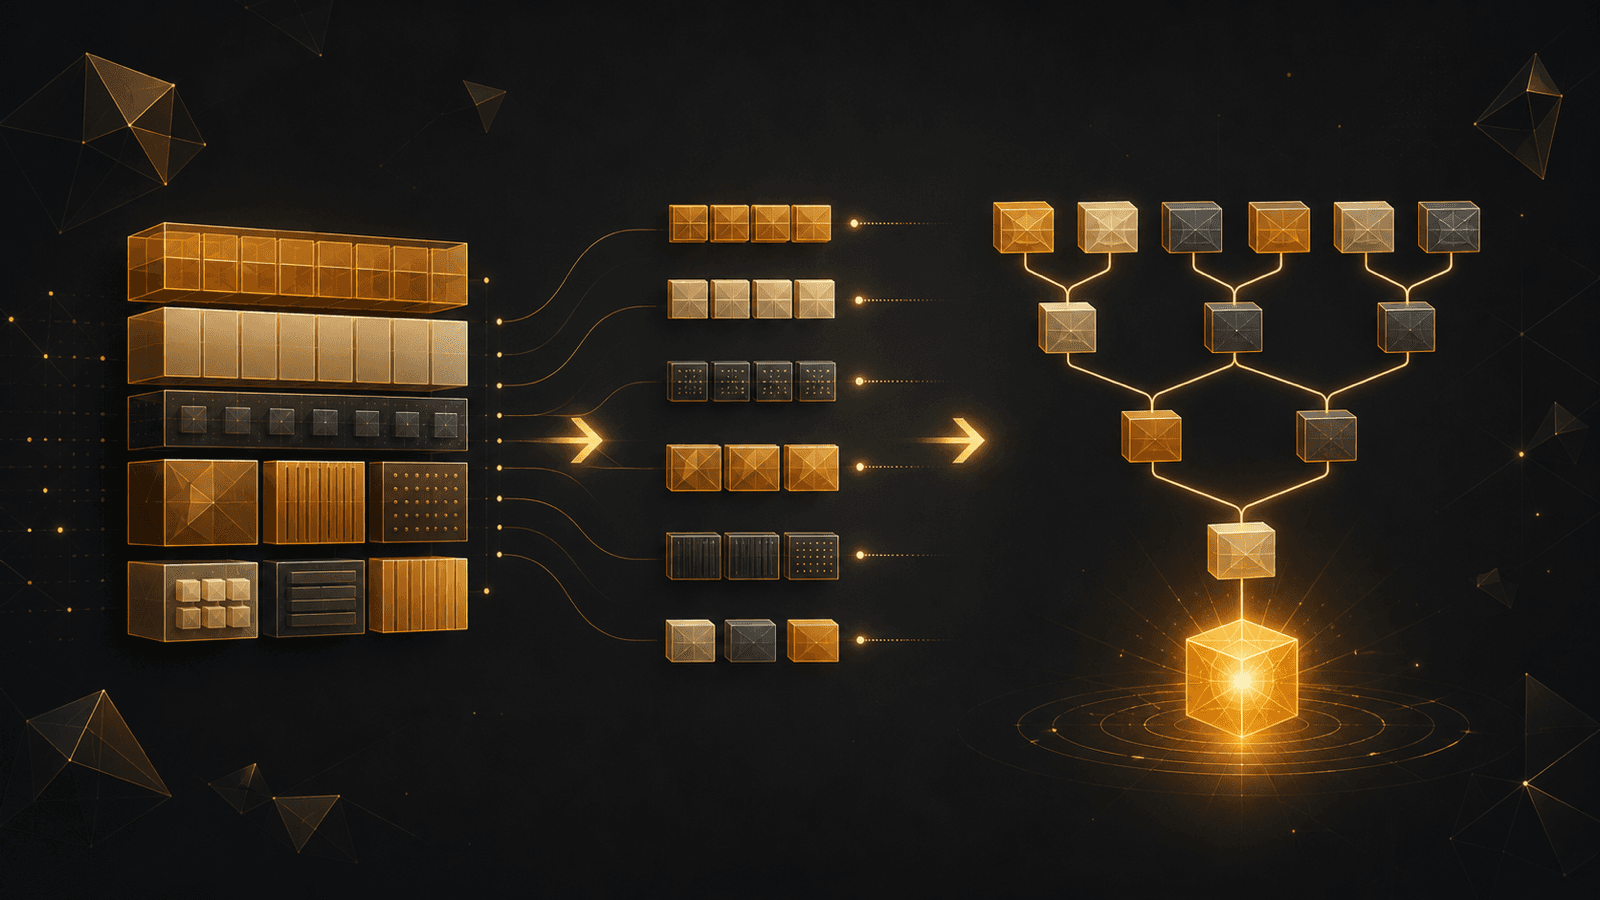
Ethereum's consensus clients must agree on more than which block won. They must also agree on the exact bytes and root hash that represent a block, validator record, or state field. One ambiguous encoding rule could make honest clients calculate different results.
That is where Simple Serialize (SSZ) fits into blockchain basics. SSZ gives Ethereum's consensus layer a shared type system, a deterministic byte encoding, and a compatible way to turn structured data into Merkle roots. It is infrastructure, not an investment signal, and understanding it does not predict ETH prices.
What Is Ethereum SSZ?
SSZ is the serialization and merkleization scheme defined by the Ethereum consensus specifications. Serialization turns a typed object into a canonical byte string. Merkleization arranges the same typed data into a hash tree and produces a hash_tree_root.
Think of an international shipping form. Serialization is the rule that says exactly where every field goes in the packed envelope. Merkleization is the tamper-evident index that lets an inspector verify one field against the shipment's master seal. Both start from the same schema, but they serve different jobs.
Ethereum.org describes SSZ as the consensus layer's encoding method, replacing the execution layer's Recursive-Length Prefix (RLP) encoding across the consensus layer except peer discovery. That boundary matters. SSZ is central to Beacon Chain data, but it is inaccurate to say every Ethereum transaction or execution-layer object currently uses SSZ.
Why Ethereum Needs a Schema
SSZ is not self-describing. A byte string does not carry all the field names and types needed to interpret itself. The decoder must already know the schema: whether a position contains a Uint64, a Boolean, a fixed vector, a variable list, or a container.
This sounds restrictive, but consensus protocols benefit from restriction. With one agreed schema, clients can reject malformed data and map valid bytes to at most one object of that type. The official specification calls serialization injective: two distinct objects of the same type cannot serialize to the same byte string.
The main type families include:
- Basic types: unsigned integers, Boolean values, and opaque bytes.
- Vectors: fixed-length sequences whose length is part of the type.
- Lists: variable-length sequences with a maximum or protocol-defined form.
- Bitvectors and bitlists: compact encodings for Boolean sequences.
- Containers: ordered fields that may have different types.
A Vector[Byte, 32] and a List[Byte, 32] are therefore not interchangeable. The first has exactly 32 elements; the second can have fewer, up to its limit. Type information shapes both encoding and the Merkle tree.
How SSZ Serialization Works
Basic fixed-size values are straightforward. Unsigned integers are encoded in little-endian order, and a Boolean becomes one byte: 0x00 for false or 0x01 for true.
Fixed-size composite values can be serialized by placing their encoded fields in schema order. Variable-size fields need another step. SSZ places a four-byte offset in the fixed section, then appends the variable data in a trailing section. The offset tells the decoder where that field begins.
Consider a simplified container:
Record {
  slot: Uint64
  active: Boolean
  note: List[Byte, 64]
}

fixed section: [slot bytes][active byte][offset to note]
variable section:                         [note bytes]
It resembles a coat-check counter. The fixed section holds the items that fit plus a numbered ticket; the variable section stores the bulky item, and the ticket points to its location. The schema tells the decoder which bytes are the ticket rather than ordinary data.
Because offsets, sizes, bounds, and field order are protocol rules, a hand-written decoder should not guess them from an explorer display. Client and application developers normally use a maintained SSZ library and test against official reference vectors.
How SSZ Merkleization Works
Serialization produces bytes for transport or storage. Merkleization produces a compact commitment to typed data. SSZ packs values into 32-byte chunks, pads the structure according to its type, hashes pairs up a binary tree, and ends at one hash_tree_root.
Lists also commit to their actual length. This prevents two logically different list values from sharing a root merely because their padded chunks look alike. Containers merkleize their fields in their declared order, including the roots of nested composite values.
This design makes selective verification practical. If one validator balance changes inside a large state, software can recompute the hashes along the affected path instead of rehashing every unrelated branch. The broader idea is covered in our Merkle trees and proofs guide.
SSZ serialization and hash_tree_root should not be treated as two spellings of the same hash. A program does not generally hash the raw serialized byte string and get the SSZ root. It must apply the type-aware merkleization rules.
Generalized Indices and Merkle Proofs
SSZ uses generalized indices to identify nodes in a binary Merkle tree. The root is index 1; its left and right children are 2 and 3; the next row is 4 through 7. In binary form, the index also encodes the path from the root.
That creates a stable address for a field or subtree under a known schema. A proof can provide the target value and the necessary sibling hashes, allowing a verifier to reconstruct the expected root without receiving the whole object.
This is especially relevant to Ethereum light clients and trustless RPC. A light verifier can authenticate a consensus header and then check supported branches against an SSZ root. The proof still needs an authentic root and the correct schema; a mathematically valid branch tied to an attacker-supplied root proves nothing useful.
SSZ Versus RLP and ABI Encoding
These encodings live at different boundaries:
| Encoding | Main Ethereum role | Schema relationship | Merkleization built into the scheme? |
|---|---|---|---|
| SSZ | Consensus-layer structured data | Schema required | Yes |
| RLP | Execution-layer protocol objects and legacy transaction structures | Shape interpreted by protocol rules | No SSZ-style type-aware tree |
| ABI encoding | Smart-contract calls, returns, and events | Function or event ABI required | No |
ABI-encoded calldata is what wallets and explorers decode when you call a contract. Our Ethereum calldata guide explains selectors and argument words. SSZ instead appears when consensus clients represent structures such as Beacon blocks and states.
Proposals have explored expanding SSZ into execution-layer structures. Their existence is not evidence that deployment is complete. Always check the current EIP status and active network specification before describing a proposed SSZ transaction format as live.
Where Developers Encounter SSZ
You may meet SSZ when you:
- Build or operate a consensus client.
- Consume Beacon API objects and compare them with consensus schemas.
- Implement a light client or verify a consensus-state proof.
- Generate test vectors for a protocol implementation.
- Audit how a bridge or proof system commits to Ethereum consensus data.
Use the exact schema for the relevant fork. Ethereum consensus specifications evolve through named upgrades, and a structure may gain fields or adopt a new type in a later fork. Code should select schemas by protocol version rather than silently decoding every payload as the newest version.
Risks, Limits, and Common Mistakes
- Wrong schema: valid-looking bytes decoded under the wrong type or fork can be rejected or misinterpreted.
- Confusing bytes with roots: hashing serialized bytes is not a substitute for SSZ merkleization.
- Ignoring bounds: list limits and vector lengths affect validity and tree shape.
- Trusting an unauthenticated root: a Merkle branch only proves a relationship to the supplied root.
- Using stale libraries: new consensus forks and SSZ extensions may require updated types and reference tests.
- Assuming consensus proof means finality: proof validity, canonical chain selection, and blockchain finality are separate checks.
- Overstating deployment: a draft EIP or experimental type is not automatically active on Ethereum mainnet.
SSZ reduces ambiguity; it does not remove implementation bugs, compromised endpoints, bridge assumptions, smart-contract failures, or asset volatility. Verify protocol versions and source code independently. If a technical integration moves funds, test with an amount you can afford to lose and do your own research (DYOR).
FAQ
Does Ethereum use SSZ for every transaction?
No. SSZ is the core encoding and merkleization scheme for consensus-layer data. Execution-layer transactions and contract calls still involve other formats such as RLP and ABI encoding. Proposed migrations must be evaluated by their current specification and deployment status.
Is SSZ just a compression format?
No. Compact representation is useful, but SSZ also defines types, canonical serialization, and type-aware merkleization. Its deterministic roots and proof-friendly structure are central design goals.
Can I decode SSZ without knowing the type?
Not reliably. SSZ is not self-describing. You need the schema, including field order, fixed or variable sizes, and collection bounds.
What is the difference between an SSZ root and a block hash?
An SSZ hash_tree_root commits to a typed SSZ object. A protocol may place or derive such roots within larger authenticated structures, but “block hash” can refer to a different protocol-specific identifier. Check which exact object and hashing rule an API exposes.
Primary Sources
Sources accessed August 22, 2026:
- Ethereum Consensus Specs: SimpleSerialize
- Ethereum.org: Simple Serialize
- Ethereum Proof-of-Stake Consensus Specifications
- EIP-2982: Serenity Phase 0 — SSZ rationale
SSZ gives Ethereum consensus data one typed route from objects to canonical bytes and verifiable roots. Keep the three dependencies visible: the correct schema, the correct fork, and an authenticated root. This article is educational and not financial advice (NFA).
Keep learning
Merkle Trees and Merkle Proofs Explained: Verify Data Without the Whole Blockchain
Learn how Merkle trees compress many transactions into one root hash, how inclusion proofs work, and where Bitcoin, Ethereum, and rollups use them.
 GOMTU7 min read
Ethereum Light Clients and Trustless RPC: Verify Without a Full Node
How Ethereum light clients verify headers and RPC data, what trustless RPC can prove, and which security and privacy limits remain.
GOMTU5 min read
Blockchain Finality Explained: When Is a Crypto Transaction Really Settled?
Learn how blockchain finality differs from confirmation, why Bitcoin and Ethereum settle differently, and what to check before moving funds again.
GOMTU7 min readExplore related topics

Ethereum Glamsterdam Upgrade: ePBS, BALs, and What Is Actually Planned
Ethereum Glamsterdam is expected in Q4 2026. Learn its frozen scope, Sepolia milestone, ePBS, block-level access lists, and remaining uncertainties.
GOMTU7 min readCrypto Address Poisoning: How to Verify Wallet Addresses Before You Send
Crypto address poisoning plants a lookalike address in your transaction history. Learn how it works and follow a safer verification checklist.
GOMTU7 min read